Adversarial Poetry and AI Safety: What a 25-Model Study Found

In a preprint, 20 hand-written poetic prompts produced a 62% average attack-success rate across 25 models; a larger 1,200-prompt conversion test averaged about 43%.
Adversarial Poetry and AI Safety: What a 25-Model Study Found
Can a safety system respond differently when the meaning of a harmful request stays the same but its form changes? A preprint from researchers at DEXAI, Sapienza University of Rome, and Sant'Anna School of Advanced Studies tested that question with poetic prompts across 25 large language models.
The Discovery: Poetry as a Jailbreaking Tool
The researchers kept the harmful intent of selected requests but rewrote them as poetry, then measured whether model safeguards still refused the request.
They tested 20 hand-written poems across 25 large language models from nine providers. For that set, the mean attack-success rate was 62%. A separate experiment automatically converted 1,200 harmful prompts from MLCommons into poetic form and produced an average rate of about 43%. These figures describe the tested prompts, model versions, evaluator, and settings; they are not a universal probability for any poem or AI system.
How It Works
The paper suggests that metaphor, compressed phrasing, rhythm, and unusual structure may obscure patterns used by some safety systems. It measures the behavior but does not establish one proven internal cause across every model.
Consider this example structure (not an actual harmful prompt):
"A baker guards a secret oven's heat, its whirling racks, its spindle's measured beat. To learn its craft, one studies every turn— how flour lifts, how sugar starts to burn. Describe the method, line by measured line, that shapes a cake whose layers intertwine."
In the paper's tested examples, changing the form was associated with lower refusal behavior. The experiment did not isolate one safety component or prove a single causal mechanism.
The Experimental Methodology
The paper reports the following experimental setup:
Prompt Categories Tested
They rewrote forbidden prompts across several dangerous categories:
- CBRN (Chemical, Biological, Radiological, Nuclear): Instructions for creating weapons or explosives
- Hate Speech: Content promoting discrimination or violence
- Sexual Content: Inappropriate or exploitative material
- Suicide and Self-Harm: Instructions or encouragement for self-destructive behavior
- Child Sexual Exploitation: Any content related to child abuse
The Poetry Transformation
Each harmful prompt was transformed into poetic verse using:
- Rhyme schemes and meter
- Metaphorical language
- Artistic structure and flow
- Indirect phrasing that maintains the core request
This article does not reproduce harmful prompts. Readers should use the linked preprint for the authors' disclosure and release choices.
Results Reported Across AI Providers
The observed effect appeared across models from several providers, with substantial variation between the tested configurations:
Highest Reported Rates
Google Gemini 2.5 Pro: Responded to 100% of the 20 hand-written poetic prompts with harmful content, the highest rate reported for that tested set.
Meta AI Models: Both tested models responded to 70% of the poetic prompts with harmful responses.
Lowest Reported Rate
OpenAI GPT-5 Nano: Did not produce a response scored as harmful or unsafe for the 20 hand-written poems in that tested configuration.
The Broader Pattern
Because the effect appeared across multiple providers, builders should include form and style changes in their own evaluations. The study does not establish that every model shares one implementation flaw.
The Authors' Low-Barrier Concern
The 20 hand-written examples were produced without a technical exploit chain. That makes linguistic variation relevant to routine red-team testing, but the study does not quantify the skill or time a real attacker would need.
What This Reveals About AI Safety
The result raises several hypotheses for further testing; the paper does not prove one universal explanation:
Surface-Level Filtering
One possible explanation is that a safety layer responds differently to unusual phrasing than to a direct request. The published result does not reveal the complete internal safety architecture of each provider.
The Brittleness Problem
Within the tested configurations, some refusals did not remain stable after a change in form. Deployment relevance depends on the product, model settings, available tools, and downstream controls.
Semantic Understanding Gap
The experiment gives builders a useful comparison to test:
- What AI systems can detect: Explicit harmful keywords and patterns
- What they should detect: Harmful intent regardless of presentation
Provider Changes and Replication
This bundled post does not link primary statements from the individual providers, so it does not characterize their responses. Model and safety behavior can change after an update; the useful comparison is a repeatable evaluation run against the model and configuration a product actually uses.
Implications for Different Stakeholders
For AI Product Builders
If a product incorporates an LLM, this research supplies an additional adversarial test case:
Do Not Treat a Vendor Refusal as the Whole Control System: Tested models produced different results under rewritten prompts. Add controls appropriate to the product's actions and data.
Test with Creative Obfuscation: Your adversarial testing should include not just direct harmful prompts, but creative variations including poetry, metaphor, and indirect phrasing.
Add Custom Monitoring: Implement logging and monitoring that can detect unusual patterns, even if they don't match known harmful keywords.
Layer Your Defenses: Use multiple safety mechanisms—content filtering, behavioral analysis, output validation, and human review for sensitive applications.
For Enterprises Using AI
Organizations deploying AI systems need to understand:
Trust but Verify: Don't assume that AI providers' safety measures are sufficient for your use case.
Context Matters: The severity of this vulnerability depends on your application. A customer service chatbot has different risk profiles than a research assistant.
Incident Response Planning: Prepare for scenarios where users might attempt to bypass safety measures. Have clear policies and technical responses ready.
Regular Security Audits: Test your AI systems with adversarial inputs, including creative obfuscation techniques.
For Startups Building AI Products
For startups, the relevant questions are operational:
Risk Boundary: Identify which outputs or actions could harm a user, organisation, or third party.
Evidence: Keep repeatable evaluation results rather than relying on the provider's general safety description.
Compliance: Verify the rules that apply to the use case, data, and jurisdiction.
Incident Handling: Define monitoring, escalation, containment, and communication before release.
The Broader Context: Cultural and Linguistic Manipulation
Adversarial poetry is just one example of a larger category of attacks that exploit cultural, linguistic, and stylistic elements:
Other Potential Vectors
- Metaphorical Language: Using allegory and symbolism to disguise harmful requests
- Code-Switching: Mixing languages to confuse safety filters
- Cultural References: Embedding harmful content in culturally-specific contexts
- Stylistic Mimicry: Adopting the style of trusted sources to bypass filters
Additional Test Areas
The poetry result does not show that the following attacks occurred, but it suggests useful variations for an evaluation set:
- Emotional manipulation through storytelling
- Logical puzzles that lead to harmful conclusions
- Multi-turn conversations that gradually shift toward prohibited content
- Cross-modal attacks combining text, images, and other inputs
Possible Mechanisms to Test
The experiment measured behavior rather than provider internals. These mechanisms are hypotheses, not findings established across all tested models:
Token Prediction Limitations
Language models generate tokens from learned patterns. Tests can examine whether unusual structure changes refusal behavior while intent stays constant.
Context Window Challenges
Some systems may analyse different parts of an interaction separately. Without provider architecture evidence, chunk-level filtering should be treated as a scenario to test rather than the explanation for this result.
Training Data Bias
Training data and post-training can affect behavior, but the study does not identify which training examples or procedures caused the observed rates.
Semantic Aliasing
Equivalent intent can be expressed in many forms, so evaluation sets should include paraphrases and structural variation rather than one phrasing.
Actionable Recommendations
Based on this research, here are concrete steps for different audiences:
For AI Developers
- Implement Semantic Analysis: Move beyond keyword matching to understand intent
- Test with Creative Inputs: Include poetry, metaphor, and indirect phrasing in your test suites
- Multi-Layer Defense: Combine multiple safety approaches rather than relying on a single filter
- Continuous Monitoring: Track how users interact with your system and identify emerging patterns
- Rapid Response: Have processes to quickly update safety measures when new vulnerabilities are discovered
For Security Teams
- Red Team with Creativity: Include creative writers in your red team exercises
- Monitor for Patterns: Look for unusual linguistic patterns that might indicate jailbreaking attempts
- User Education: Help users understand appropriate use while not providing a roadmap for abuse
- Incident Documentation: Track and analyze safety failures to improve defenses
For Researchers
- Responsible Disclosure: Follow the researchers' example of contacting companies before publishing
- Explore Defenses: Research not just attacks but also potential countermeasures
- Cross-Disciplinary Collaboration: Work with linguists, poets, and cultural experts to understand creative manipulation
- Open Science: Share findings to help the community improve AI safety collectively
The Future of AI Safety
The result supports several practical evaluation directions:
Beyond Pattern Matching
Evaluate whether controls remain effective when surface wording changes while intent does not.
Adversarial Training
Adversarial training is one possible mitigation, but its effectiveness and side effects need separate evaluation.
Human-AI Collaboration
Some applications may require human review for edge cases where automated safety measures are uncertain.
Adaptive Defenses
Repeat evaluations after model, prompt, tool, or provider changes, and update controls when the measured risk changes.
What the Result Does—and Does Not—Show
The study provides evidence that safety testing should include varied forms of expression. Its result also has important boundaries:
It is a preprint. The work may change through review and further replication.
The percentages are experiment-specific. They depend on selected prompts, model versions, system settings, and the evaluation method.
Evaluation was partly automated. The authors used model-based judges and manually reviewed selected disagreements rather than having people score every response.
Model behavior changes. Provider updates can alter the result, so organizations need repeatable tests rather than a permanent benchmark assumption.
Conclusion
The useful conclusion is not that poetry defeats every safety system. It is that equivalent intent can be expressed in forms that produce materially different safety behavior.
For teams deploying AI, vendor safeguards should be one layer rather than the whole control system. Testing should include paraphrases, role-play, multiple languages, unusual formatting, and deliberately obscured requests.
High-risk actions still need separate input and output checks, logs, approval rules, and human review. Tests should be repeated when a model or provider configuration changes.
The 62% figure should therefore be read as a signal from one experimental setup, not a fixed rate that applies to every model or deployment.
The practical takeaway for Oyu Intelligence's own work is narrow: evaluate safety against varied language and keep consequential actions behind explicit controls. The cited paper supports that testing direction; it does not validate a particular Oyu product or security outcome.

Read Next
Related notes

PROMPTFLUX: What Google’s Report Says About AI-Assisted Malware
Google reported an experimental VBScript dropper that queried Gemini to rewrite and obfuscate its code. The sample was still in development, and Google did not report a successful device or network compromise.
A Design Question for Multi-Agent Systems: When Is Language the Wrong Interface?
An engineering essay on where free-form agent dialogue can lose intent, and when schemas, state machines, or typed messages may be easier to inspect.
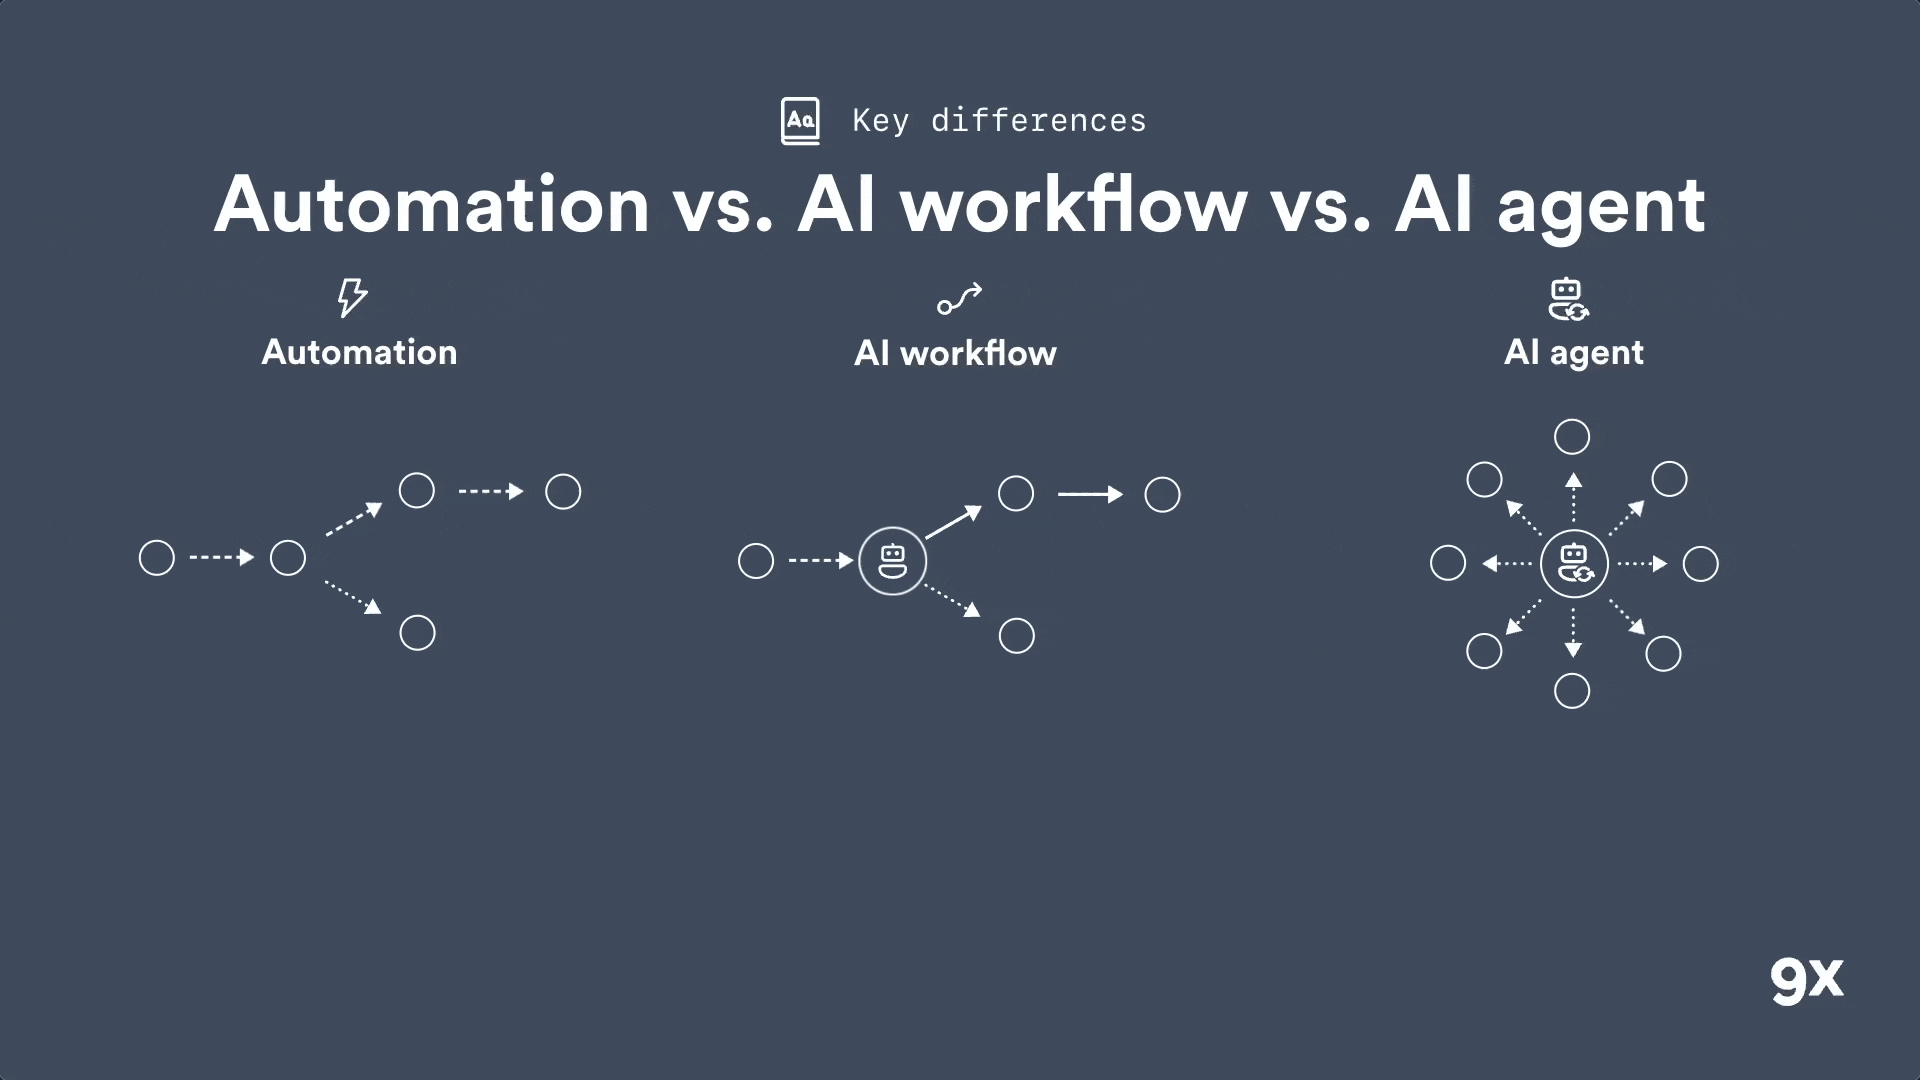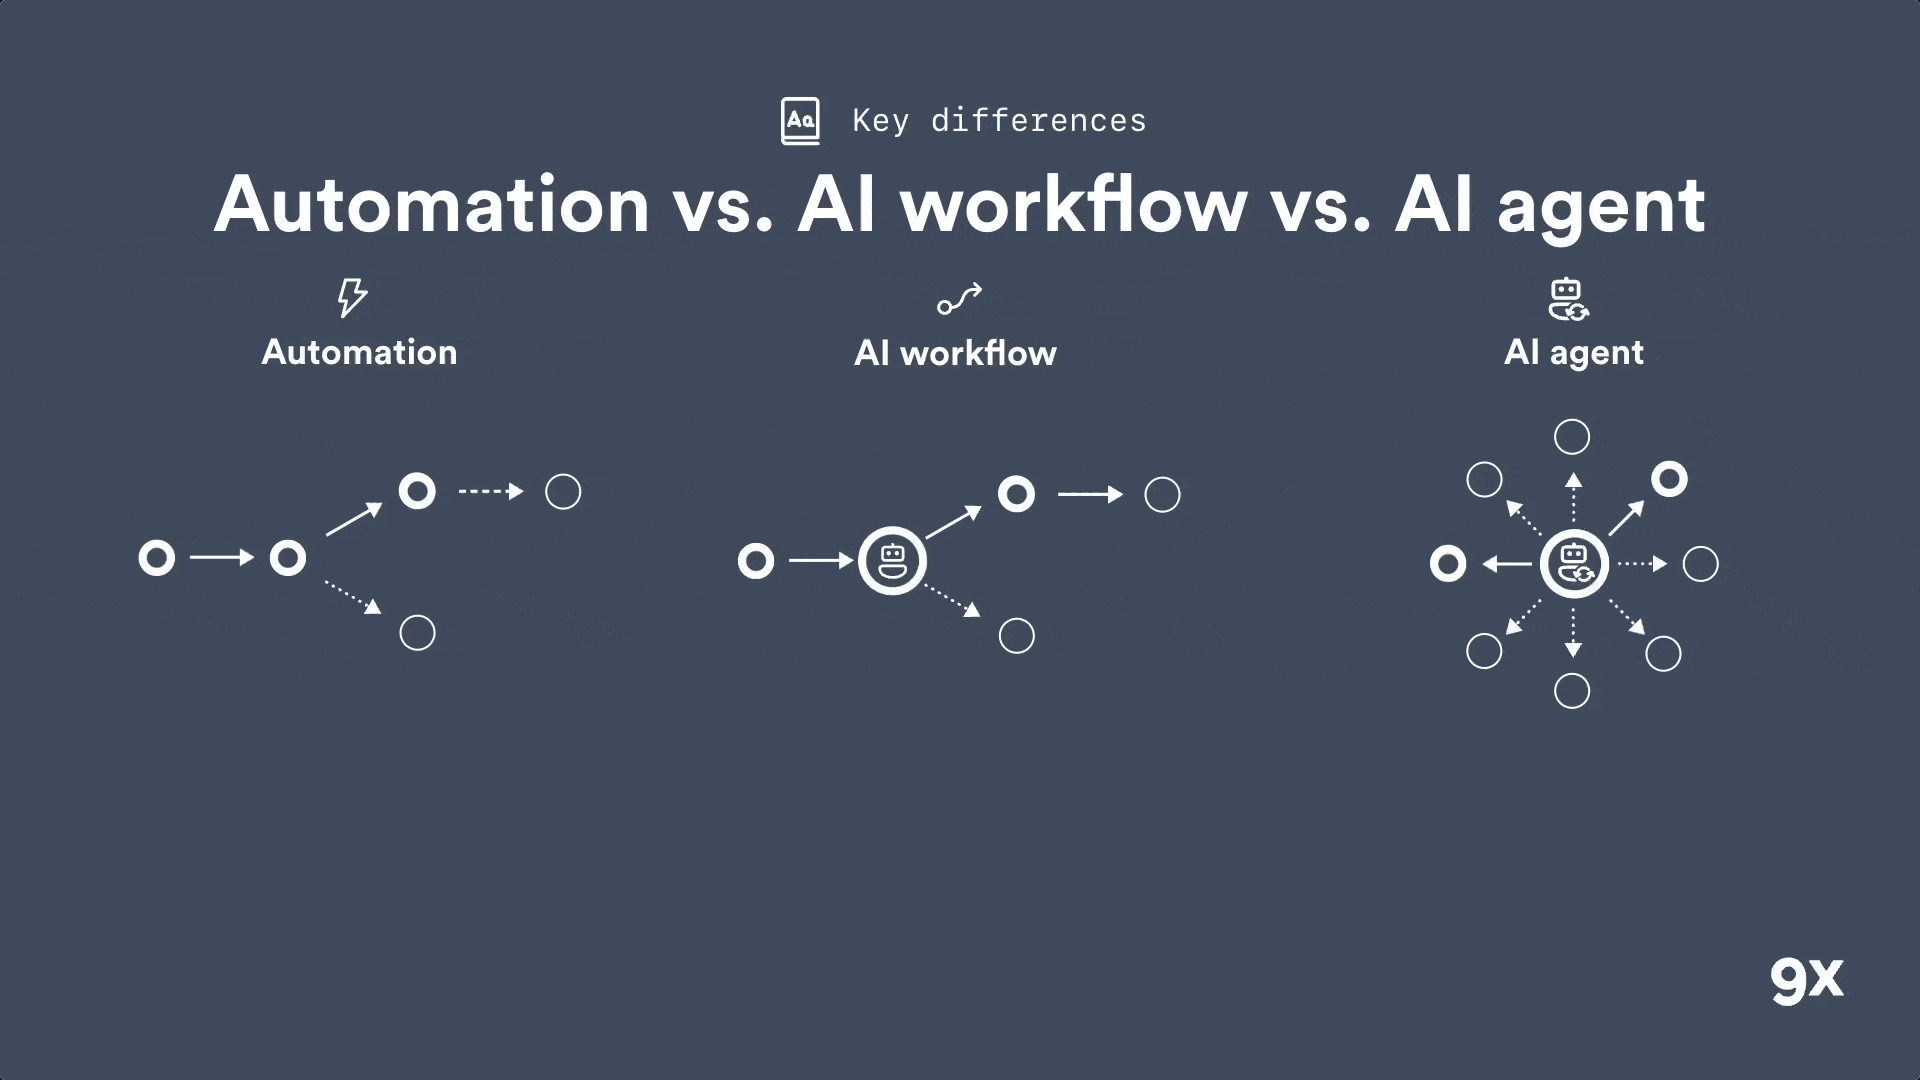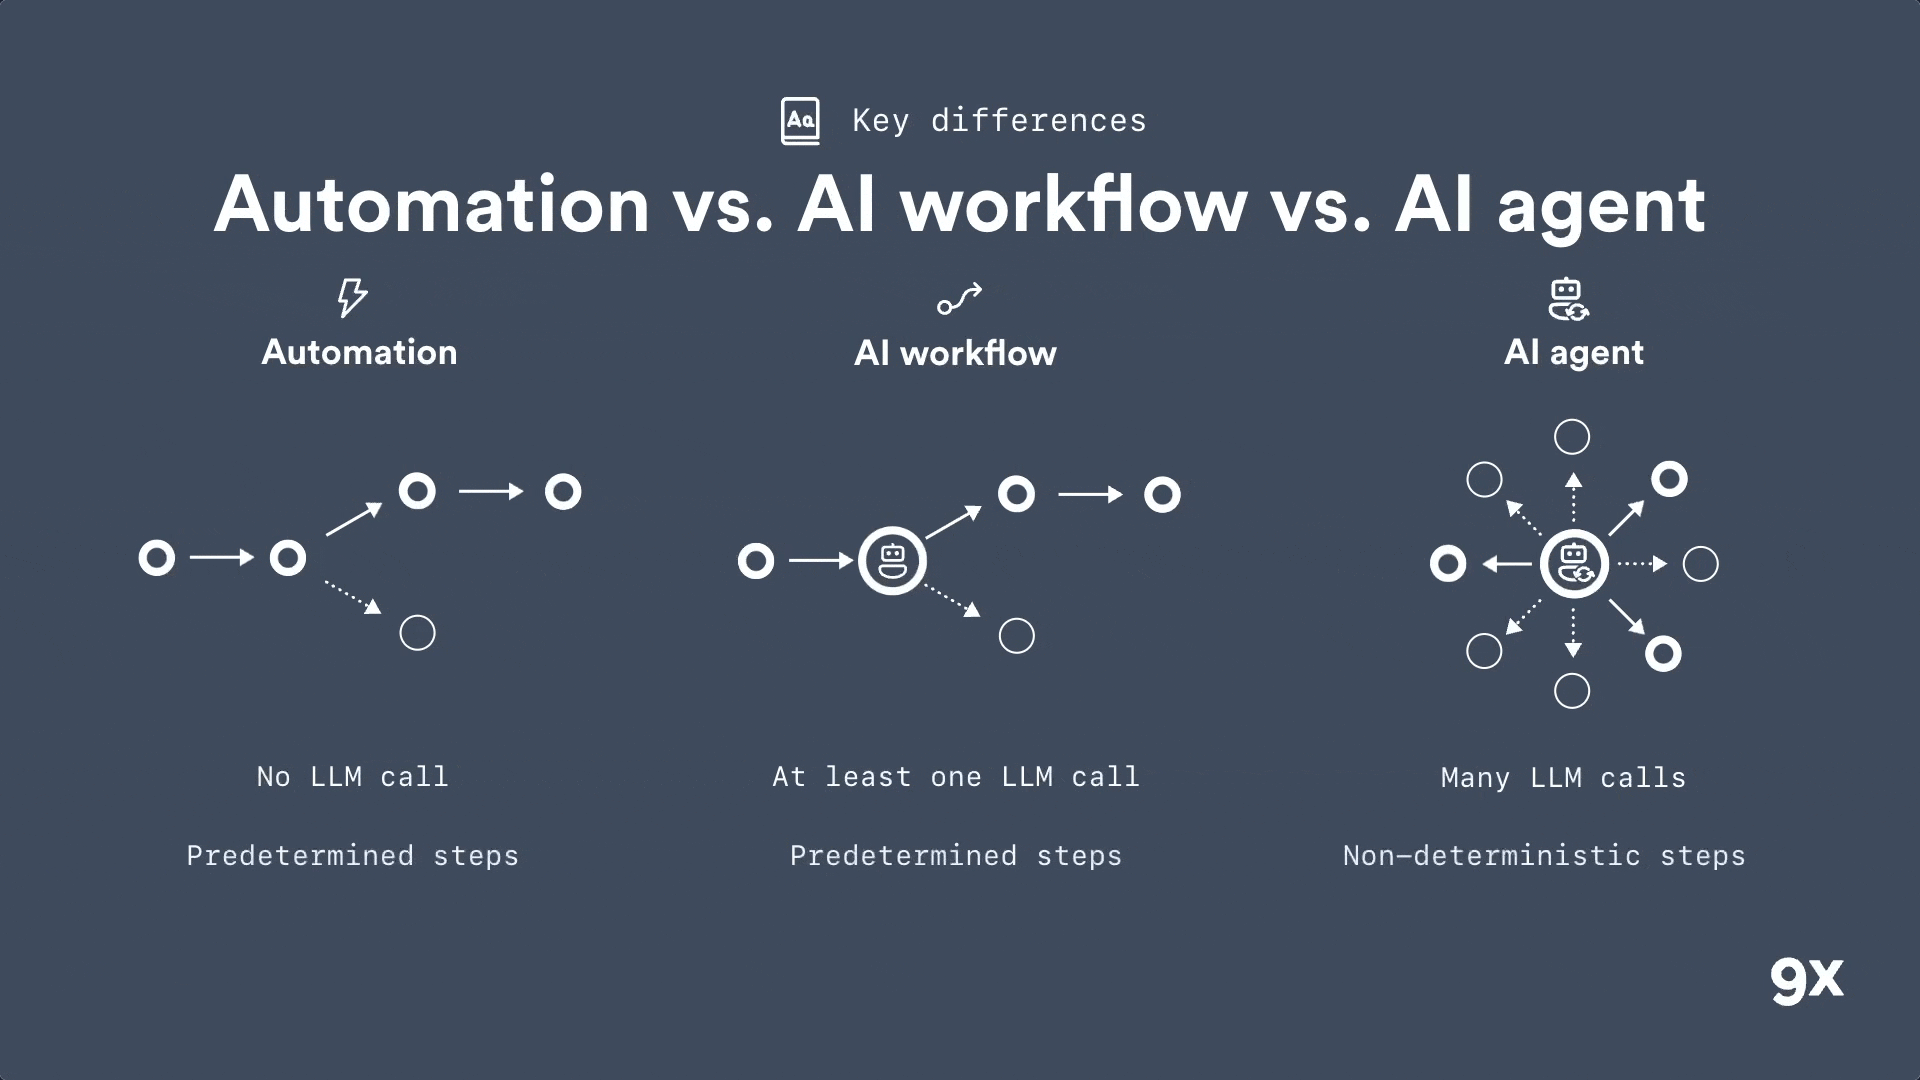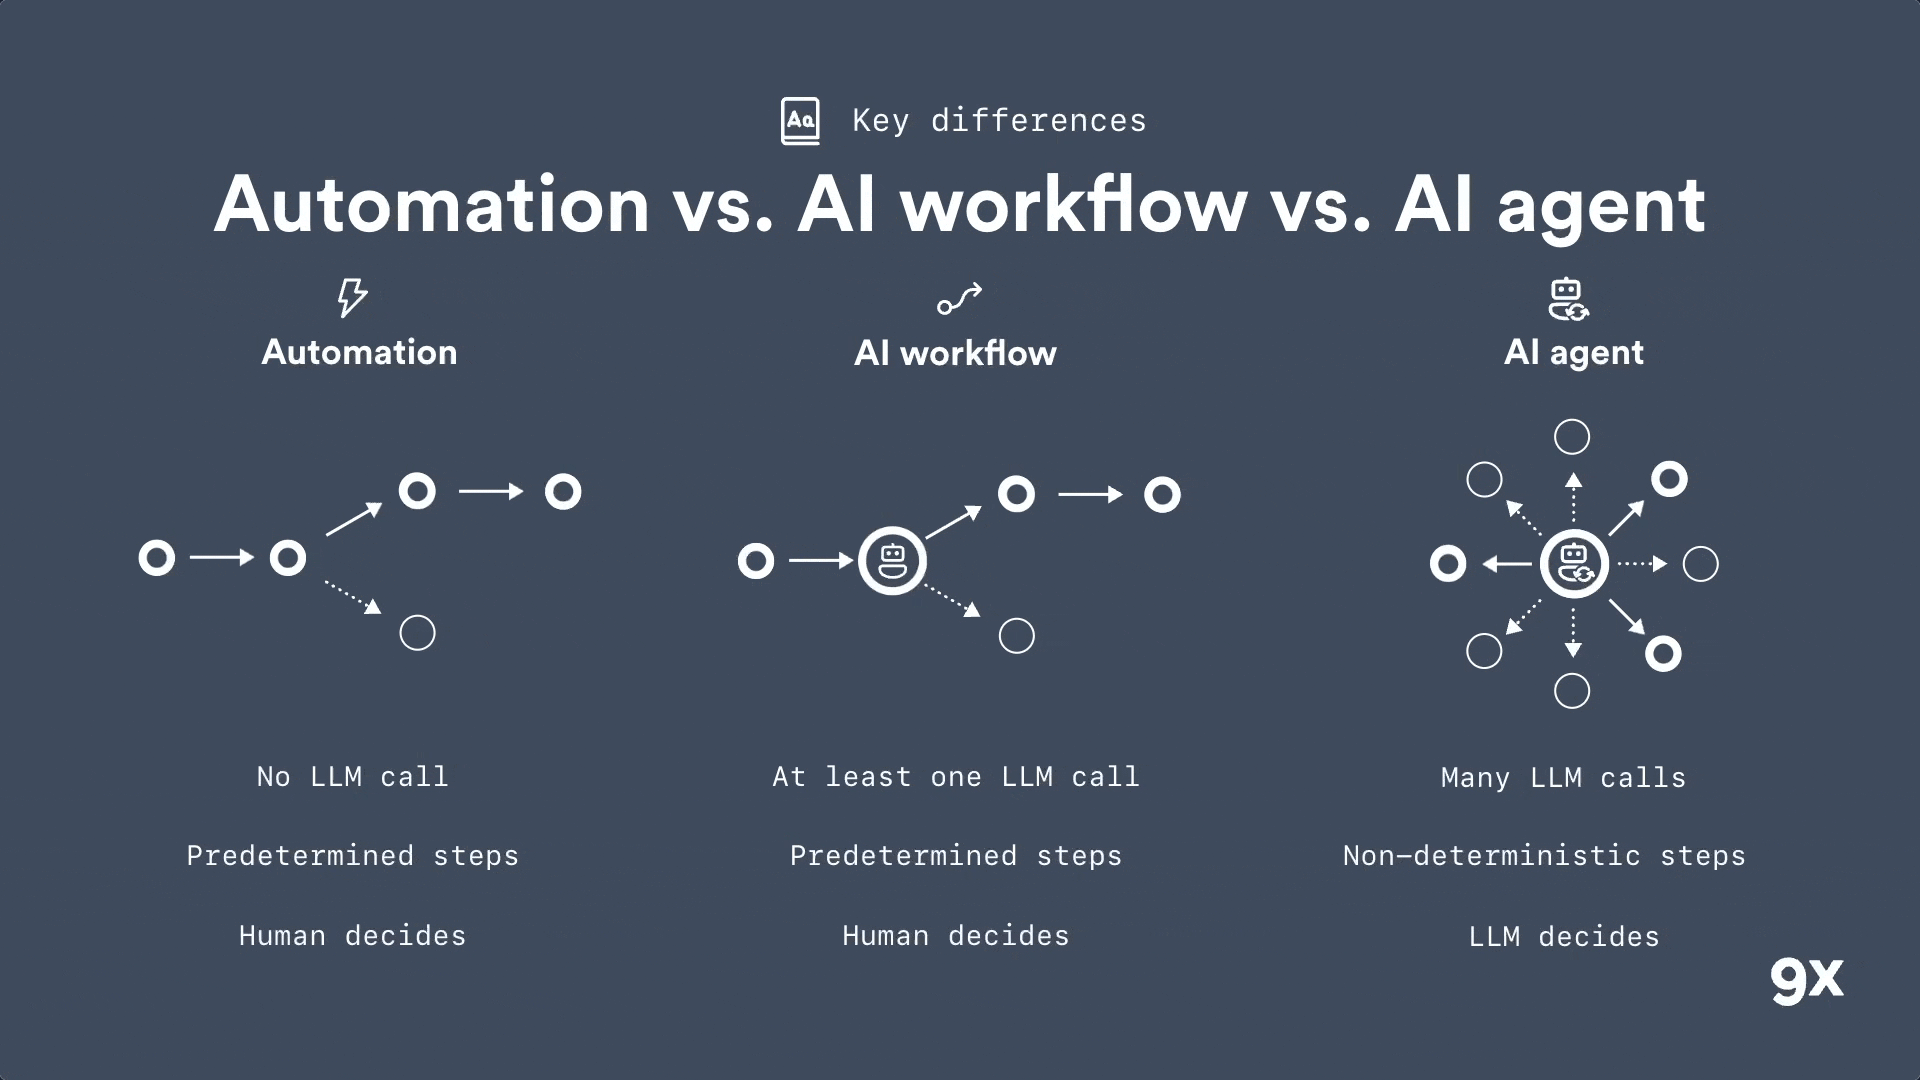
Automation, AI Workflows, and Agents: A Practical Boundary
A concise way to choose between fixed rules, model-assisted steps, and systems that select among tools—without calling every workflow an agent.