The AI Landscape in 2025: A Historical Snapshot
An archived 2025 overview of AI markets, technology, and policy. Several market and regulatory statements lack linked sources and should be rechecked before current use.
The AI Landscape in 2025: A Historical Snapshot
This article records how the AI market, technology, and policy landscape was described in early 2025. It is an archived snapshot, not current market, legal, or investment guidance. Claims without a linked primary source should be verified before reuse.
What This Source Can Support
The original 2025 article cited an AI market value above $1.8 trillion and named healthcare, finance, retail, and manufacturing as major adoption areas. No underlying market report is linked in this source, so the figure and category ranking cannot be independently verified here.
The material is more useful as a list of topics that teams were evaluating than as a market-size or adoption report.
Technology Areas Discussed in 2025
Language Models
Language models were being evaluated for drafting, classification, retrieval, coding assistance, and other bounded workflow steps. Capability varied by model, language, task, configuration, and evaluation method.
Multimodal Systems
Systems that accept combinations of text, images, audio, or video expanded the range of possible interfaces. Accepting a format does not establish that a model understands it reliably enough for a particular decision.
Edge and Hosted AI
Teams could choose between hosted services, on-device processing, or a hybrid based on latency, privacy, cost, connectivity, and maintenance requirements. The appropriate architecture depends on the use case rather than a trend label.
Systems That Select Actions
Robotics, logistics, and software agents were common areas of discussion. In any safety-sensitive setting, action boundaries, fallback behavior, monitoring, and human authority need to be defined before claims about autonomy or reliability can be made.
Candidate Use Cases, Not Proven Outcomes
The original article listed examples in finance, healthcare, education, and manufacturing. These are better treated as hypotheses to evaluate:
- classifying or routing records in a controlled workflow;
- assisting review of images, documents, or sensor readings;
- drafting material for a qualified person to check;
- detecting selected anomalies against an agreed definition; and
- forecasting or recommending options with a documented baseline.
None of these examples proves accuracy, savings, safety, or adoption. Each requires representative data, an acceptance measure, exception handling, and a named owner.
Policy Is Jurisdiction- and Date-Specific
The original article summarized policy activity in the United States, European Union, China, Japan, and India without linking the underlying legal texts. Regulation, executive policy, implementation dates, and guidance can change. Any operational or compliance decision should therefore use current official sources for the relevant jurisdiction.
Risks and Operating Questions
Before introducing a model-assisted workflow, teams should define:
- which records the system may access and retain;
- who is accountable for the output and any resulting action;
- how accuracy, bias, latency, and operating cost will be measured;
- what happens when the model is uncertain, unavailable, or wrong; and
- how users can review, correct, or appeal a consequential result.
Forecasts Are Not Delivery Evidence
The original text included forecasts for 2025–2030 involving wider business adoption, improved reliability, autonomous systems, scientific discovery, and artificial general intelligence research. Those statements were projections, not verified outcomes. They should not be used to justify a purchase or product claim without current evidence.
A Practical Evaluation Sequence
- Name one repeated task and its current baseline.
- Define the allowed inputs, actions, and prohibited data.
- Test with representative cases, including failures and edge cases.
- Compare quality, time, cost, and exception rates with the existing process.
- Assign review, incident response, and shutdown responsibility before release.
Archived Resource
The original Mongolian PDF is retained with this post as a historical companion. Its figures, case studies, and forecasts should be checked against their original sources before current use.
📄 Download our comprehensive AI research document: Download our comprehensive AI research document (PDF)
Conclusion
The durable lesson from this 2025 snapshot is to separate a usable capability from a forecast. Model quality, price, regulation, and provider terms change, so decisions require current sources and a bounded use case.
Responsible implementation requires clear ownership, data and permission boundaries, evaluation, and a way for people to review consequential output.
For Oyu Intelligence, this archived article is background material rather than proof of company capability or customer results.

Read Next
Related notes

Adversarial Poetry and AI Safety: What a 25-Model Study Found
In a preprint, 20 hand-written poetic prompts produced a 62% average attack-success rate across 25 models; a larger 1,200-prompt conversion test averaged about 43%.

PROMPTFLUX: What Google’s Report Says About AI-Assisted Malware
Google reported an experimental VBScript dropper that queried Gemini to rewrite and obfuscate its code. The sample was still in development, and Google did not report a successful device or network compromise.
A Design Question for Multi-Agent Systems: When Is Language the Wrong Interface?
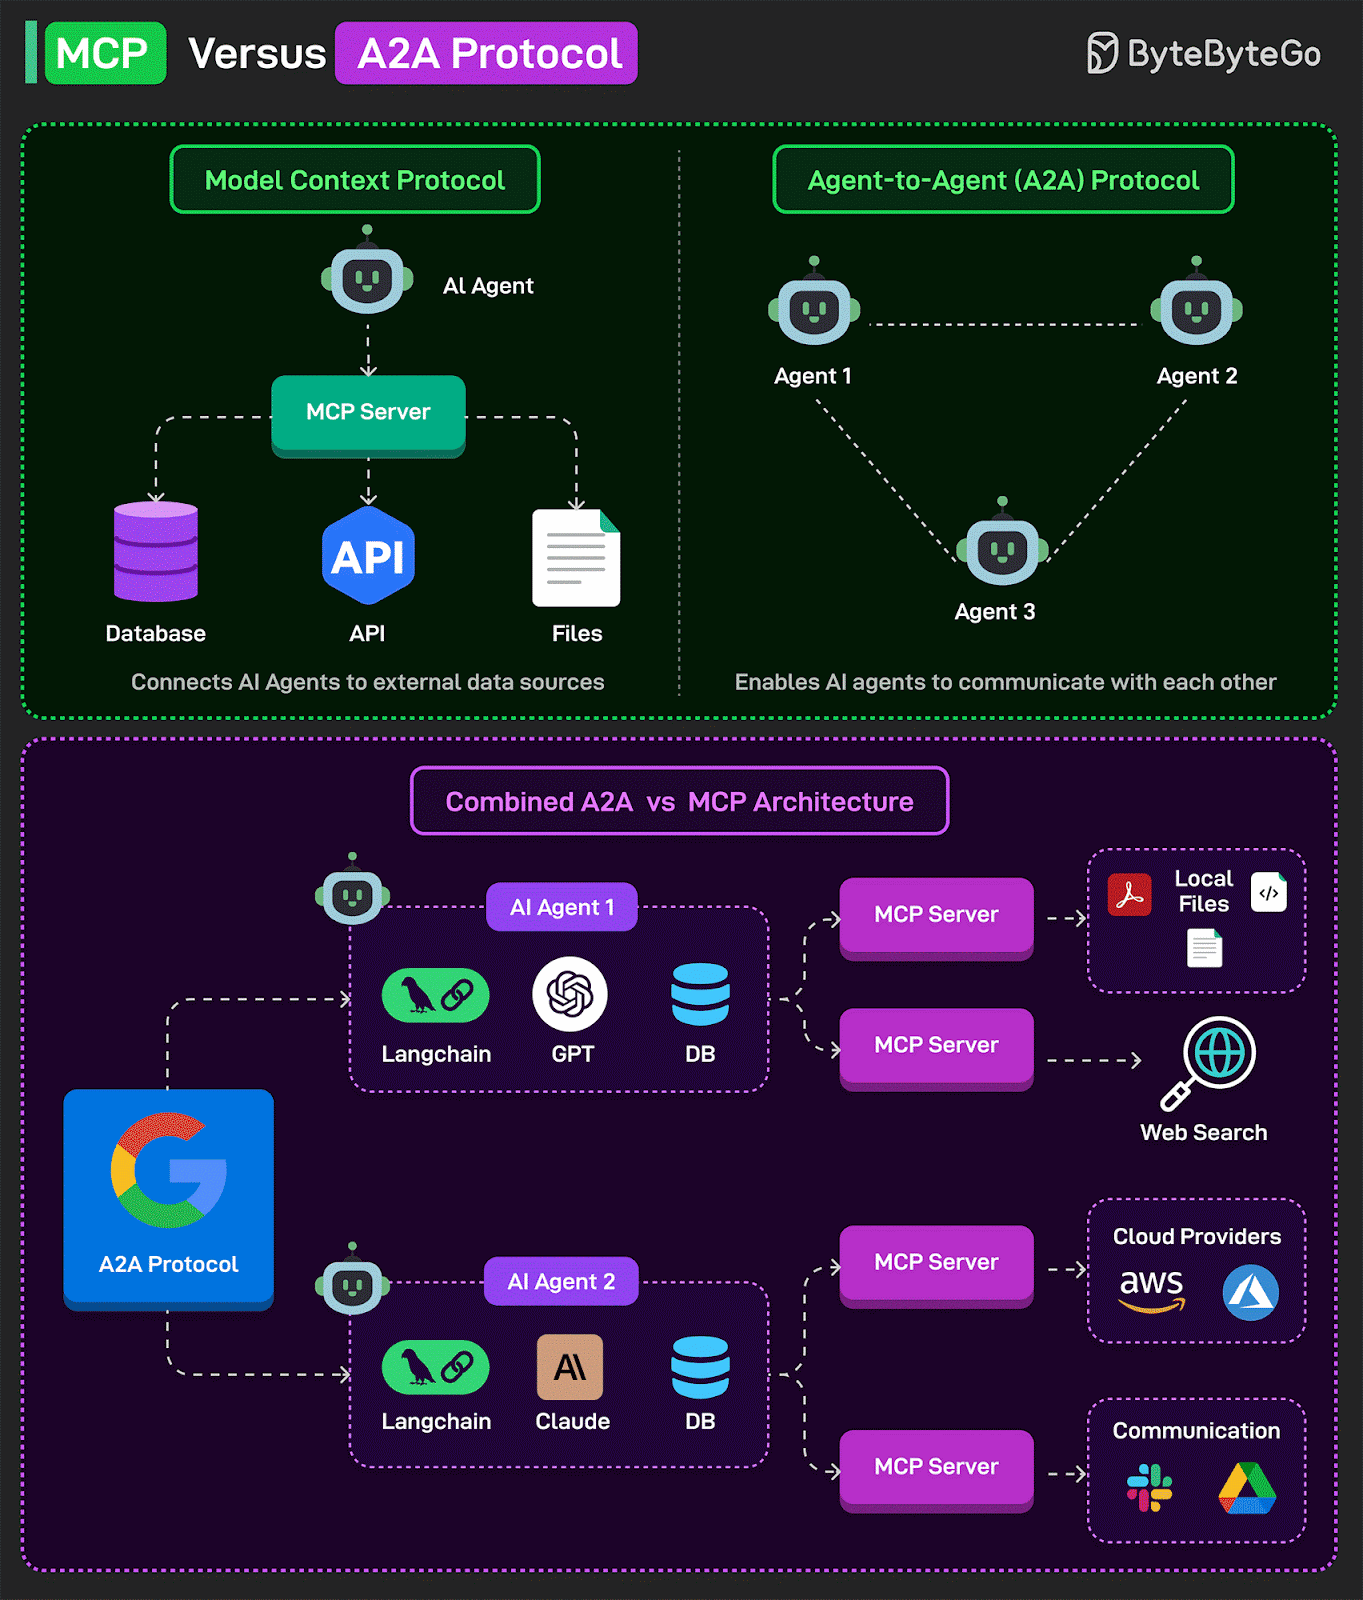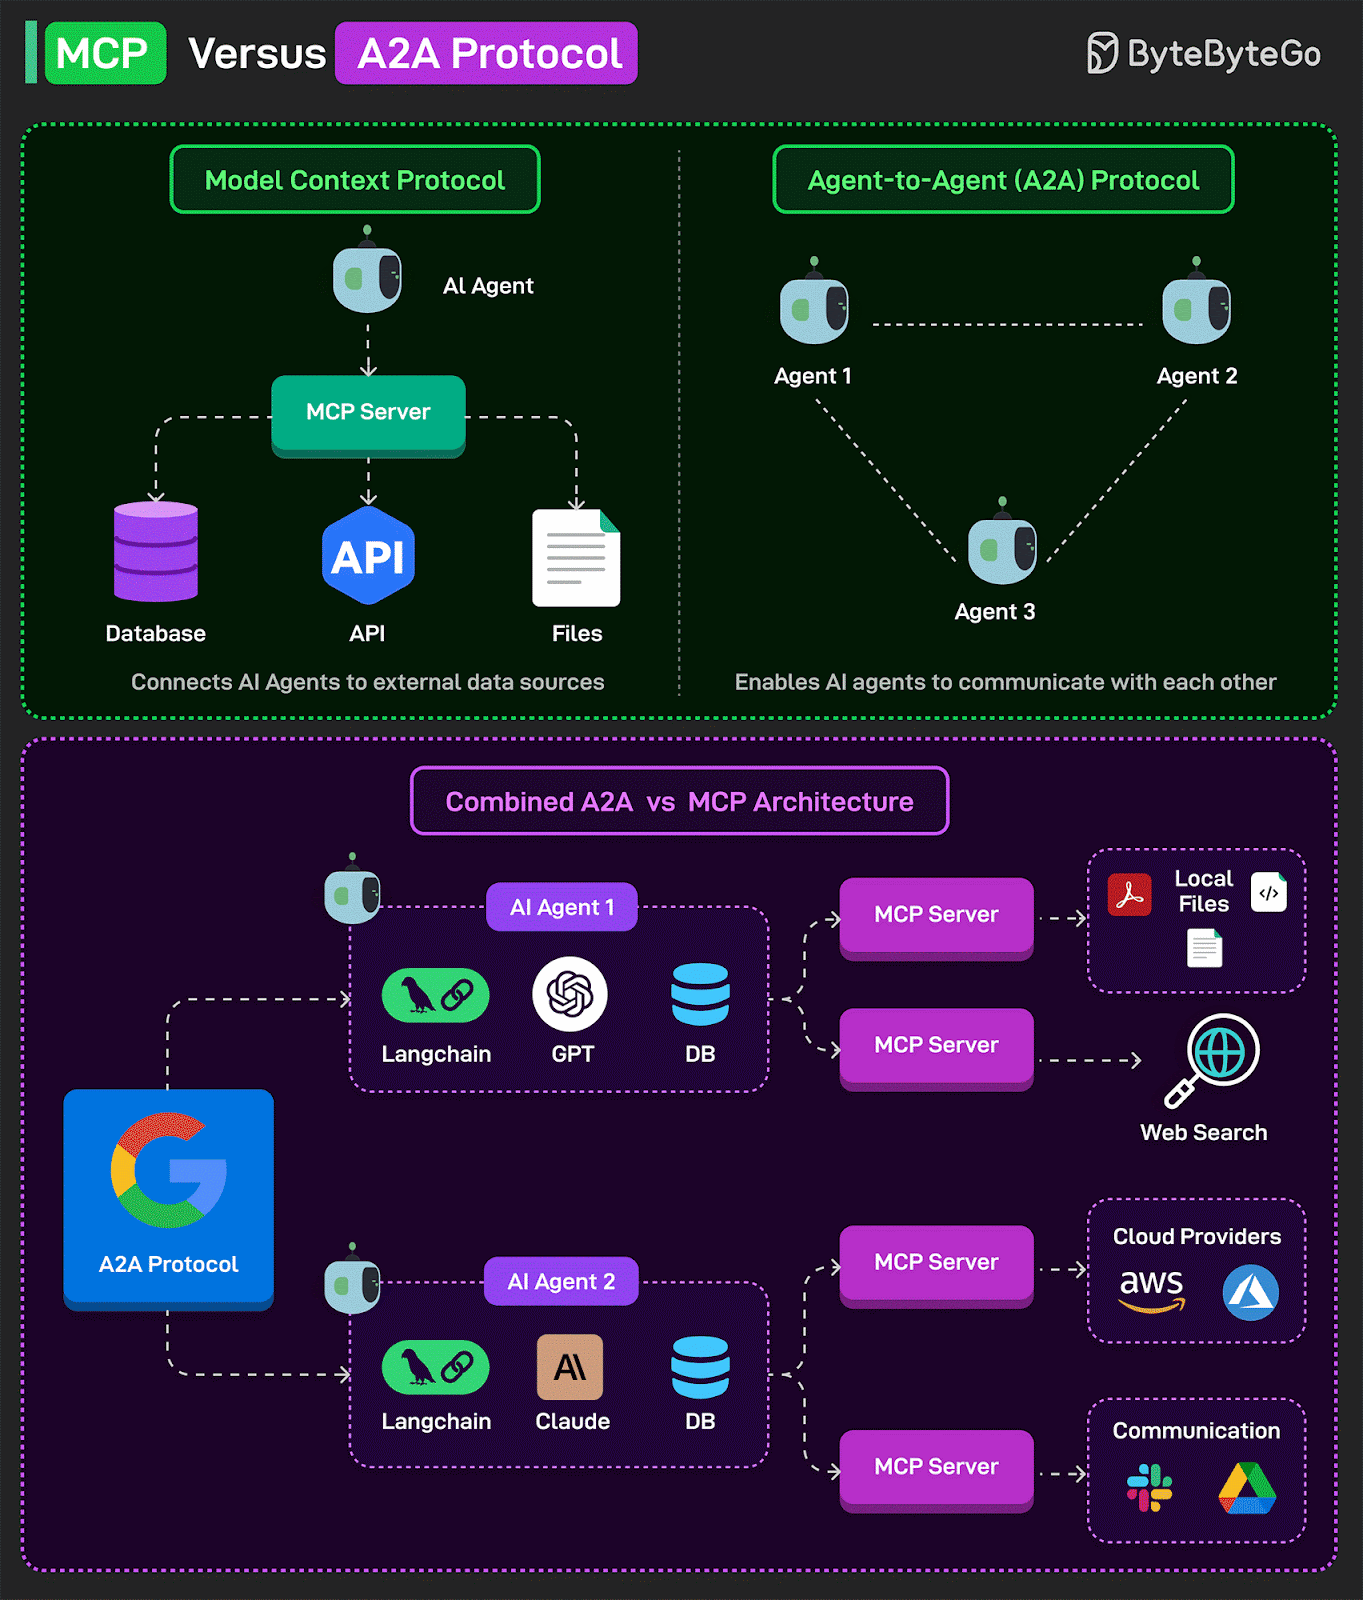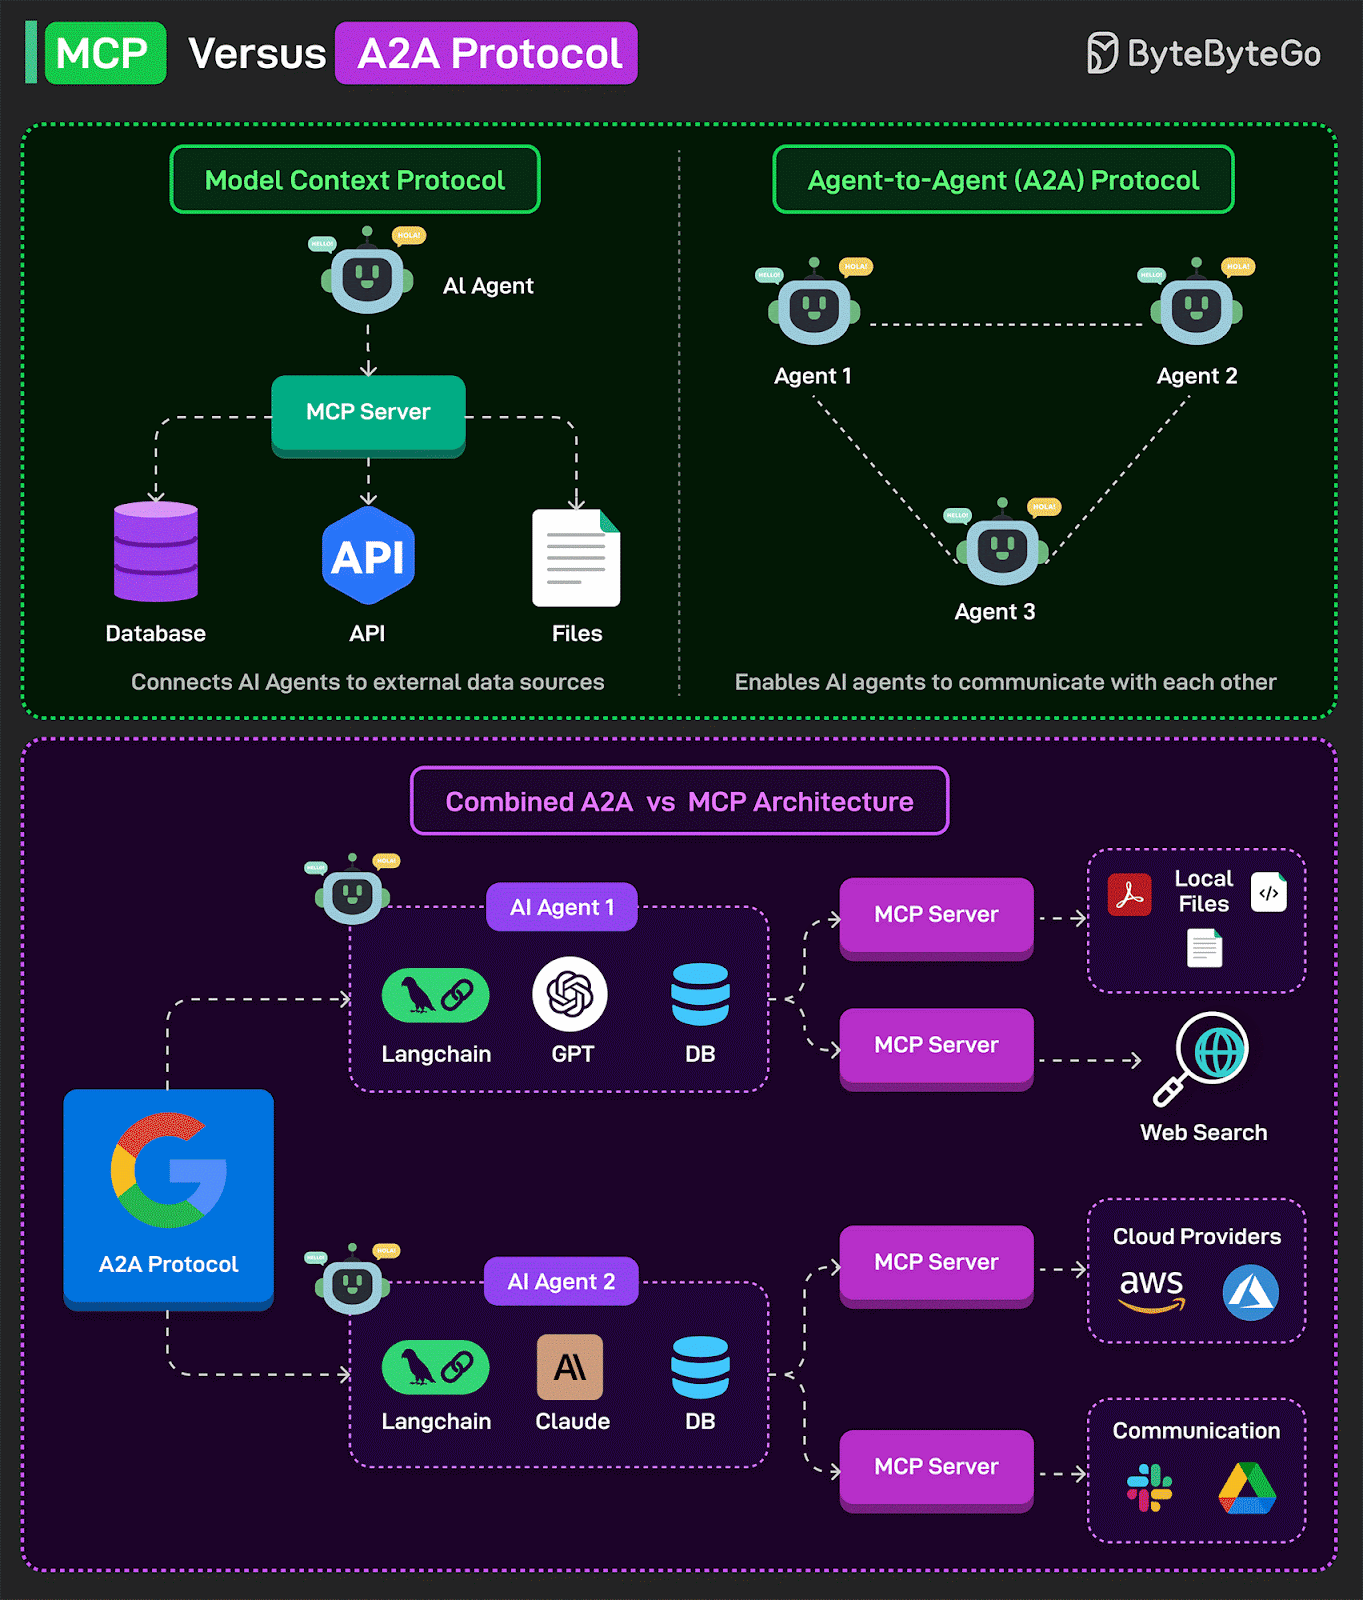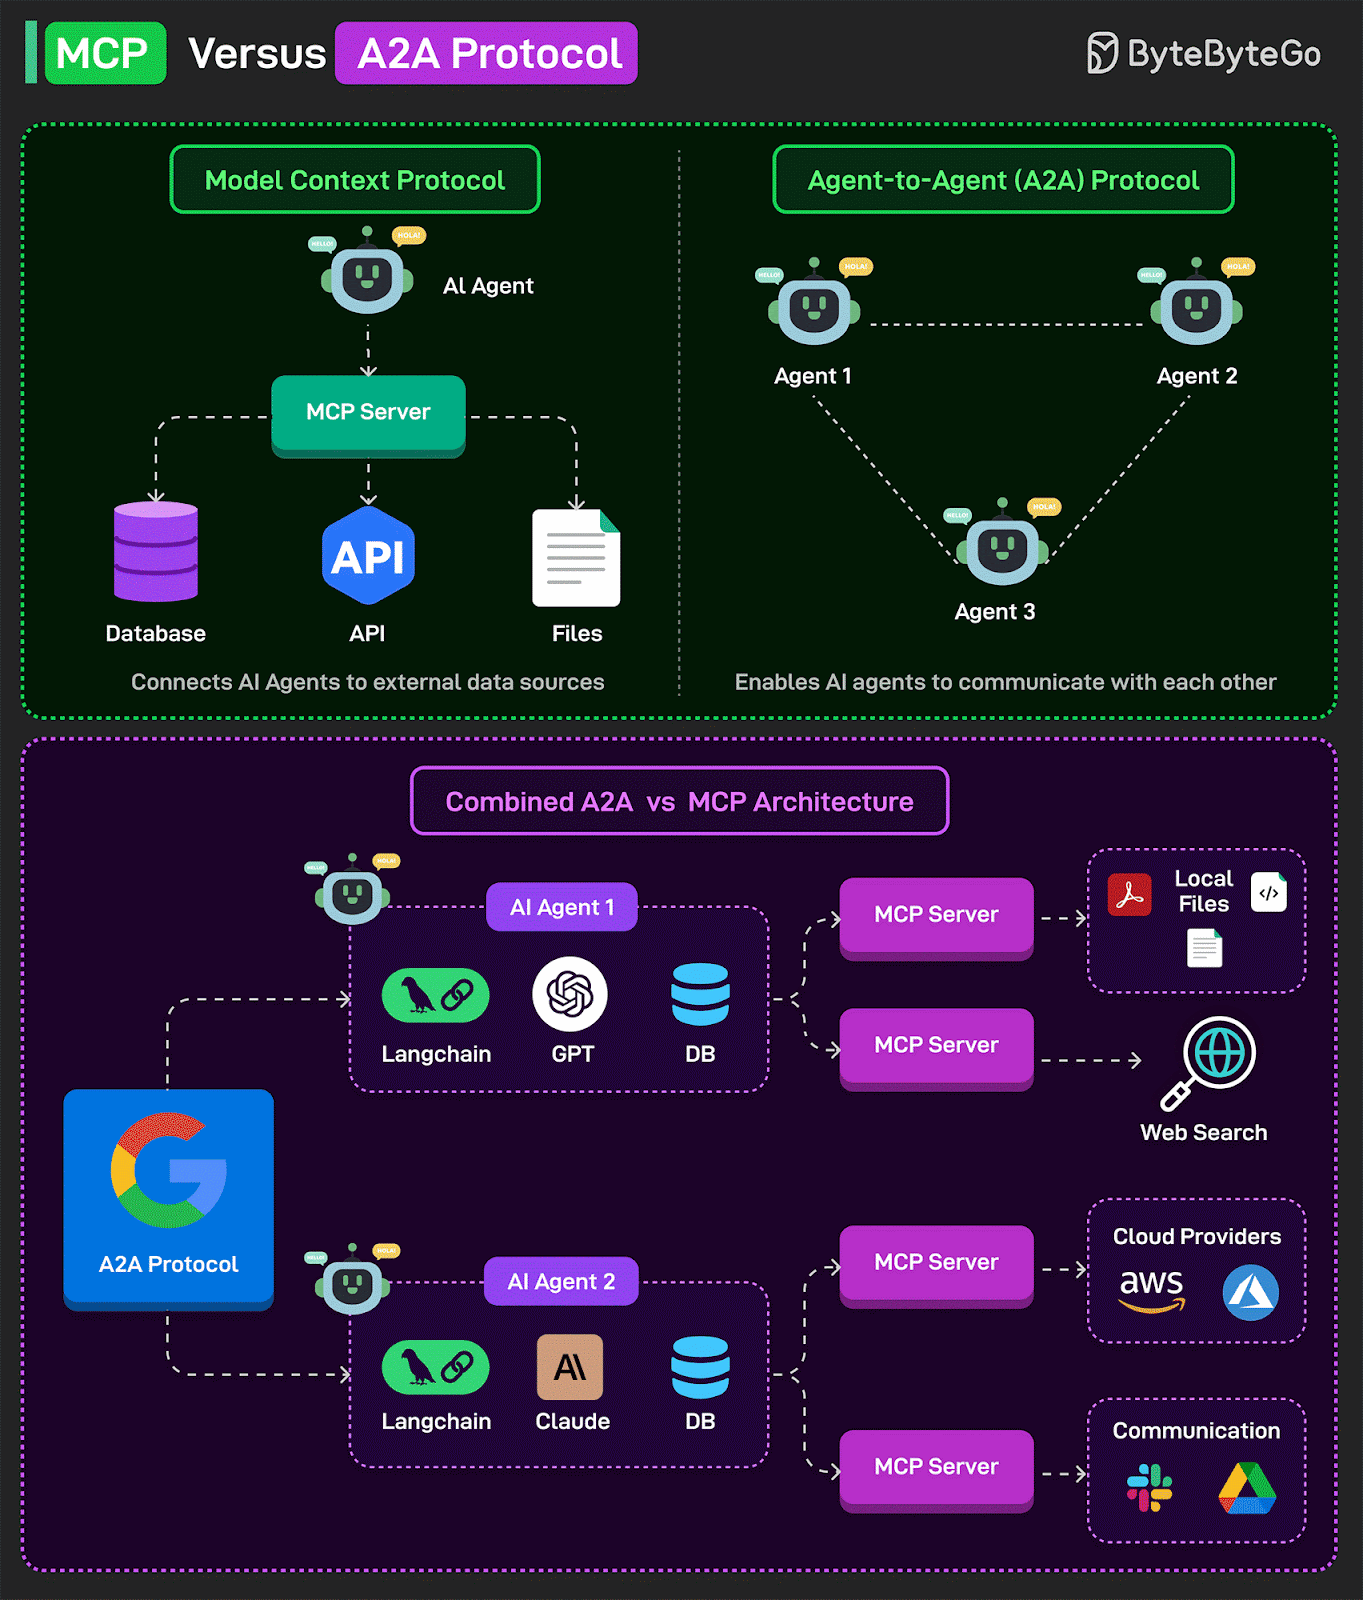
An engineering essay on where free-form agent dialogue can lose intent, and when schemas, state machines, or typed messages may be easier to inspect.